The team behind SoMark open-sources OXR, the first document parser with RSI. It turns PDFs and document images into Agent-Friendly data with SOTA accuracy and speed.
New York, NY (PRUnderground) October 20th, 2026
The team behind SoMark today announced the open-source release of OXR (Optical Everything Recognition), a 1.3-billion-parameter document parsing model. It turns PDFs and document images into Agent-Friendly data in Markdown or JSON, with layout coordinates and reading order. The release combines what the team reports as state-of-the-art(SOTA) accuracy and parsing speed with a recursive self-improvement (RSI) loop used during post-training.
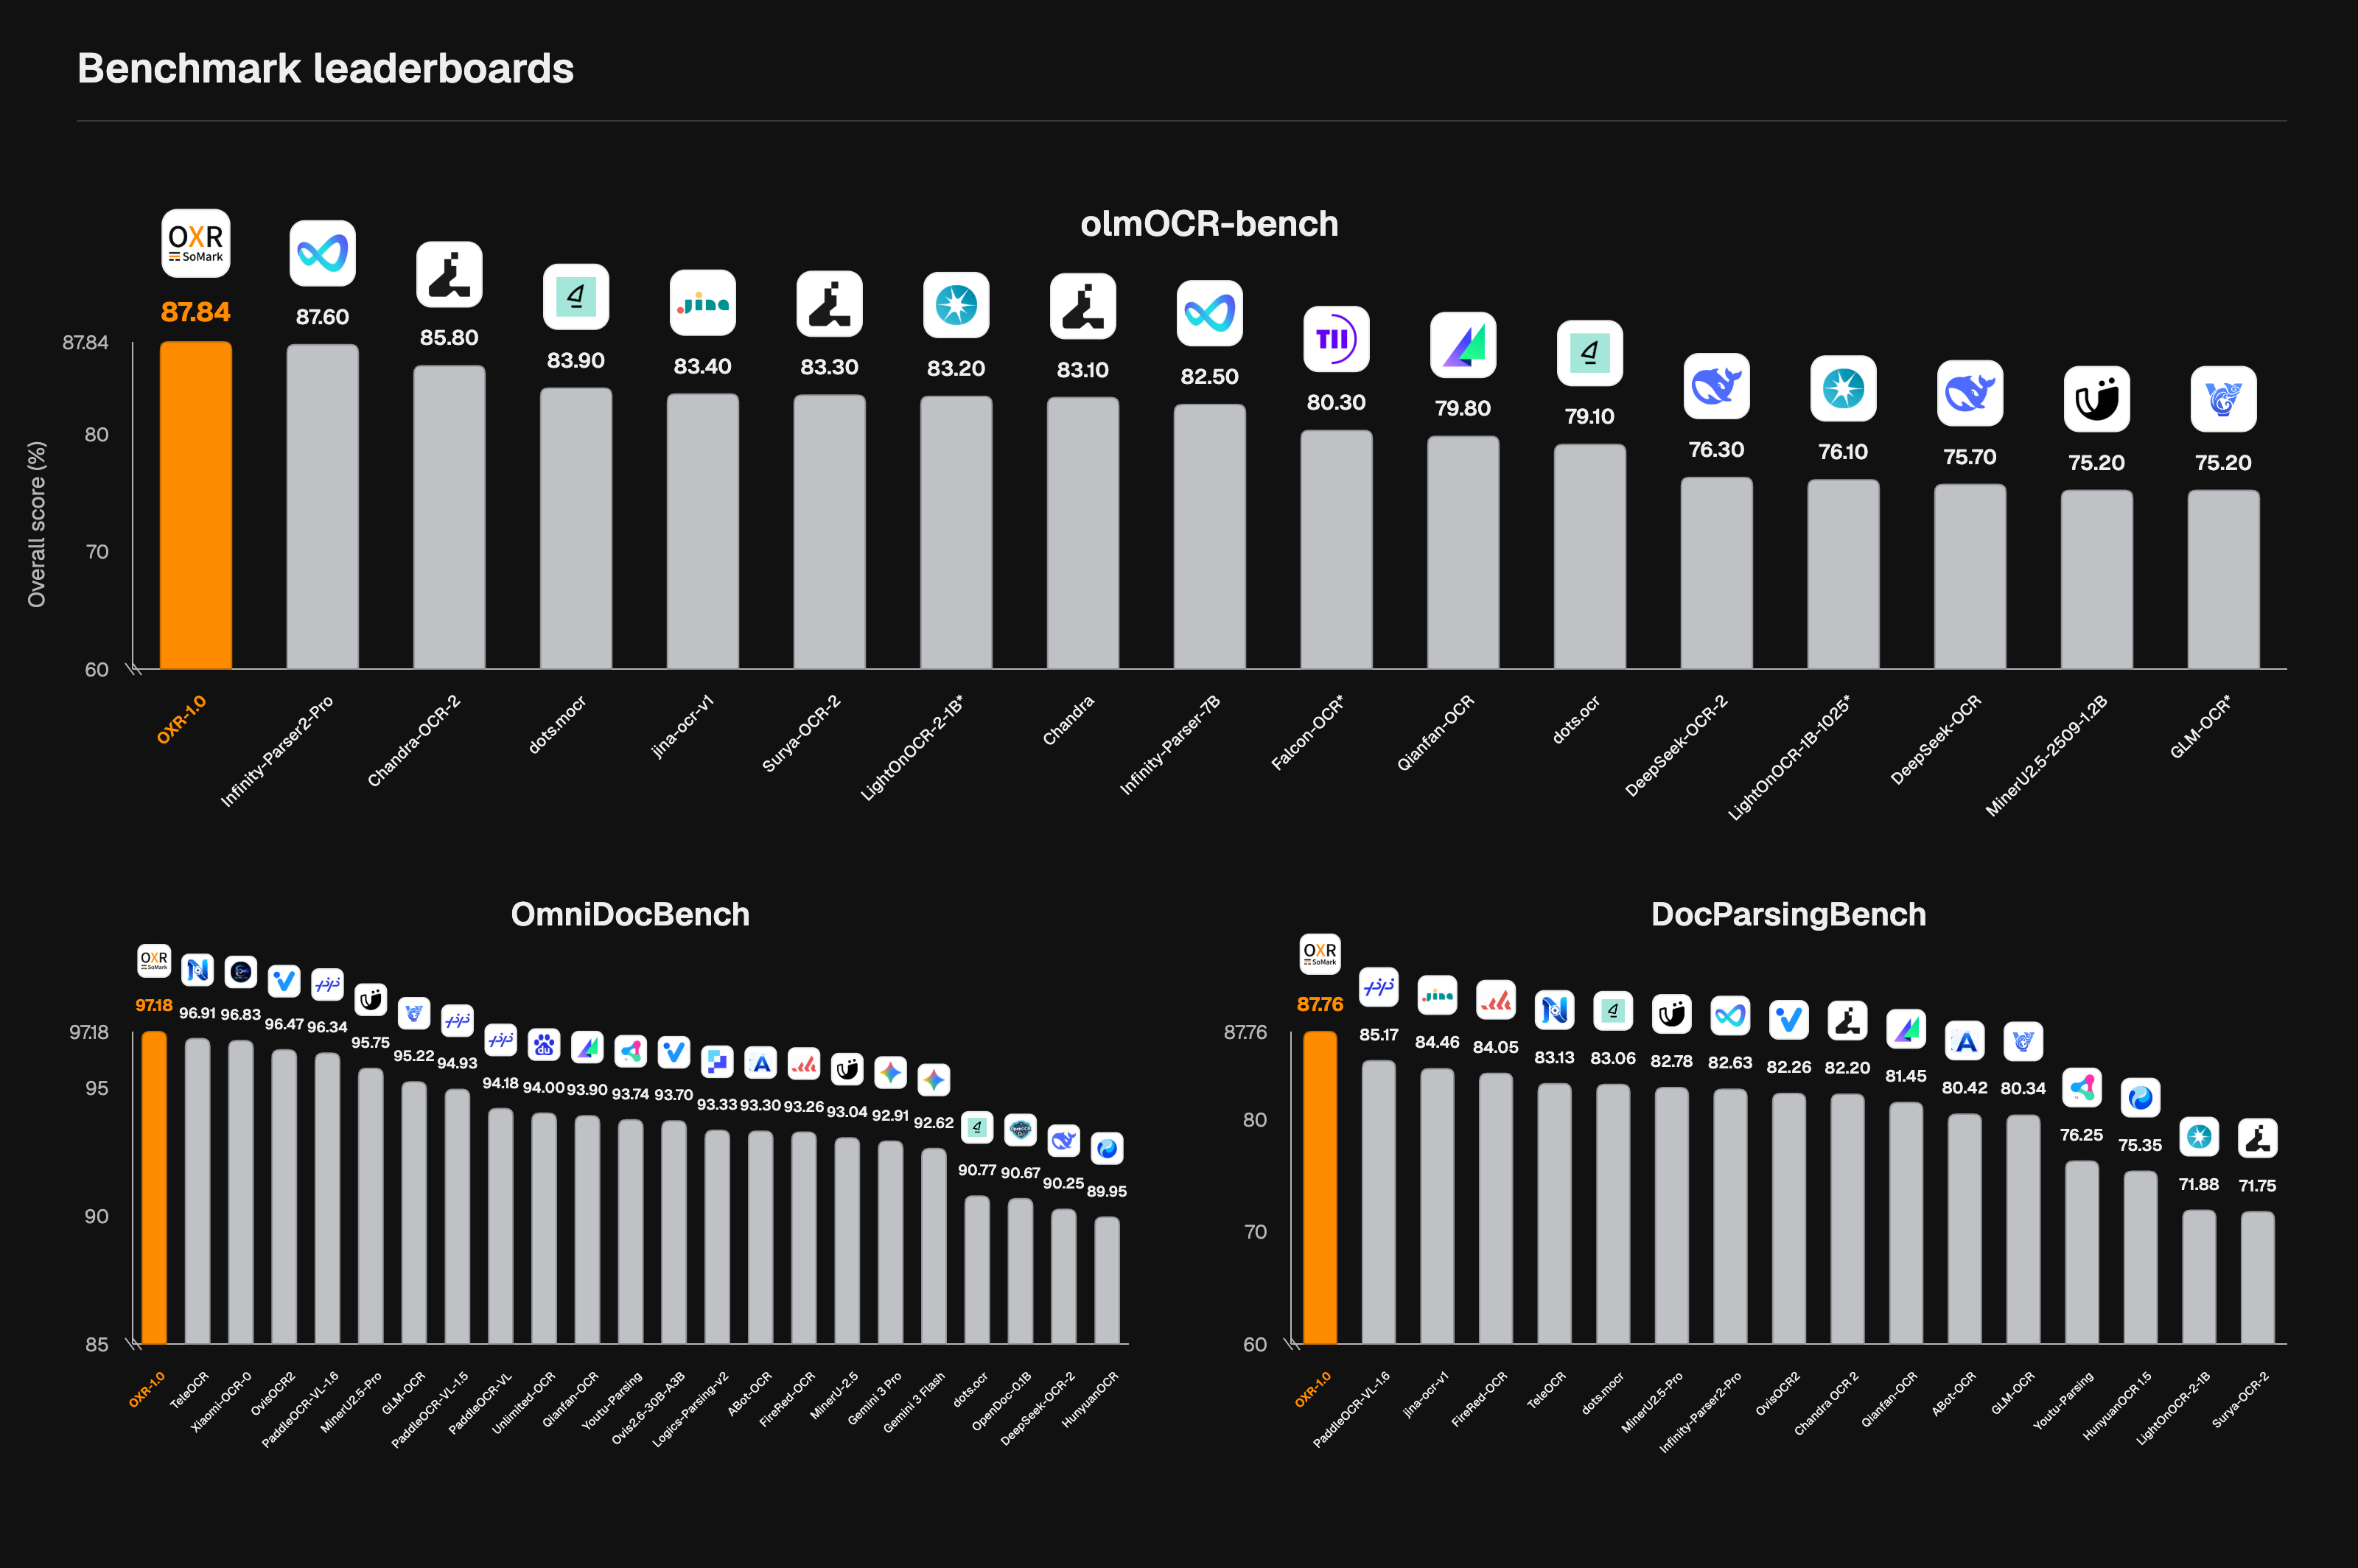
According to the evaluation report, OXR ranks No. 1 on olmOCR-Bench, OmniDocBench, and DocParsingBench. The accuracy comparisons use published peer-model scores. In separate end-to-end speed tests on a single RTX PRO 6000, it ranked first among 21 compared models on the same 100-page OmniDocBench subset.
OXR recognizes 13 document element types, including tables, formulas, chemical equations, chemical structures, and code blocks. Supported inputs include challenging documents and layouts, such as A3 exam papers, newspapers, vertical text, and handwritten content. It preserves document structure and reading order in its output, with layout coordinates linking parsed content to its position on the original page. This supports downstream retrieval and agent workflows. The model is intended for AI builders developing LLM applications, RAG systems, agents, and document workflows, as well as document AI researchers and open-source developers.
"Real documents keep exposing new weaknesses. Turning those failures into training data usually requires diagnosing the problems and manually labeling new samples," said Binyang Qiu, founder and CEO of SoMark. "We wanted to speed up model iteration without waiting for another round of manual data preparation."
To address this evolving long-tail challenge, OXR incorporates an RSI loop into its post-training process, marking what the team describes as the first application of this approach in document parsing. The loop uses parsing errors and uncertain results to plan the next training round and generate targeted training data.
In each round, OXR parses unlabeled documents. A general vision-language model (VLM) evaluates OXR outputs and analyzes errors and uncertainty, while disagreement across OXR rollouts also identifies uncertain samples. A clustering model groups these issues by cause. The general VLM then develops a training plan and generates targeted training data for OXR's next training round.
This loop requires no manual labeling of new training data, speeding up model iteration.
While RSI supports continued model improvement, organizations also need parsing output that matches their own document standards. Even for the same document, businesses may define element categories, region boundaries, and grouping rules differently. OXR keeps layout analysis (LA) independent and pluggable, so teams can replace the built-in layout model while retaining OXR's recognition and reading-order capabilities.
OXR's task-level architectural redesign also supports faster parsing. Recognition and reading order run in parallel within the same model, avoiding the delay of a separate reading-order step. Layout analysis remains independent, so a lighter model can handle that task while preserving layout accuracy.
OXR's source code is available on GitHub, and its model weights are available on Hugging Face, allowing developers to run the model locally. The project uses an Apache 2.0-based custom license with additional terms, as specified in the project's LICENSE file.
About OXR and SoMark
OXR is a 1.3B open-source document parsing model from the team behind SoMark. It ranks #1 on olmOCR-Bench, OmniDocBench, and DocParsingBench and delivers SOTA parsing speed. The model uses a recursive self-improvement (RSI) loop during post-training.
SoMark is a production-grade document parsing engine for agents, powered by an independent model. It supports more file formats, finer-grained recognition of document elements, and faster processing. It also offers extensive post-processing features, custom development, and model training services for different business needs.
